KlustronDB Read-Write Separation Solution
KlustronDB Read-Write Separation Solution
KlustronDB database clusters support read-write separation internally within the database and are transparent to applications. User applications do not need to make any modifications to use the database's read-write separation feature, thereby significantly improving the overall system performance and hardware utilization.
1. Overview
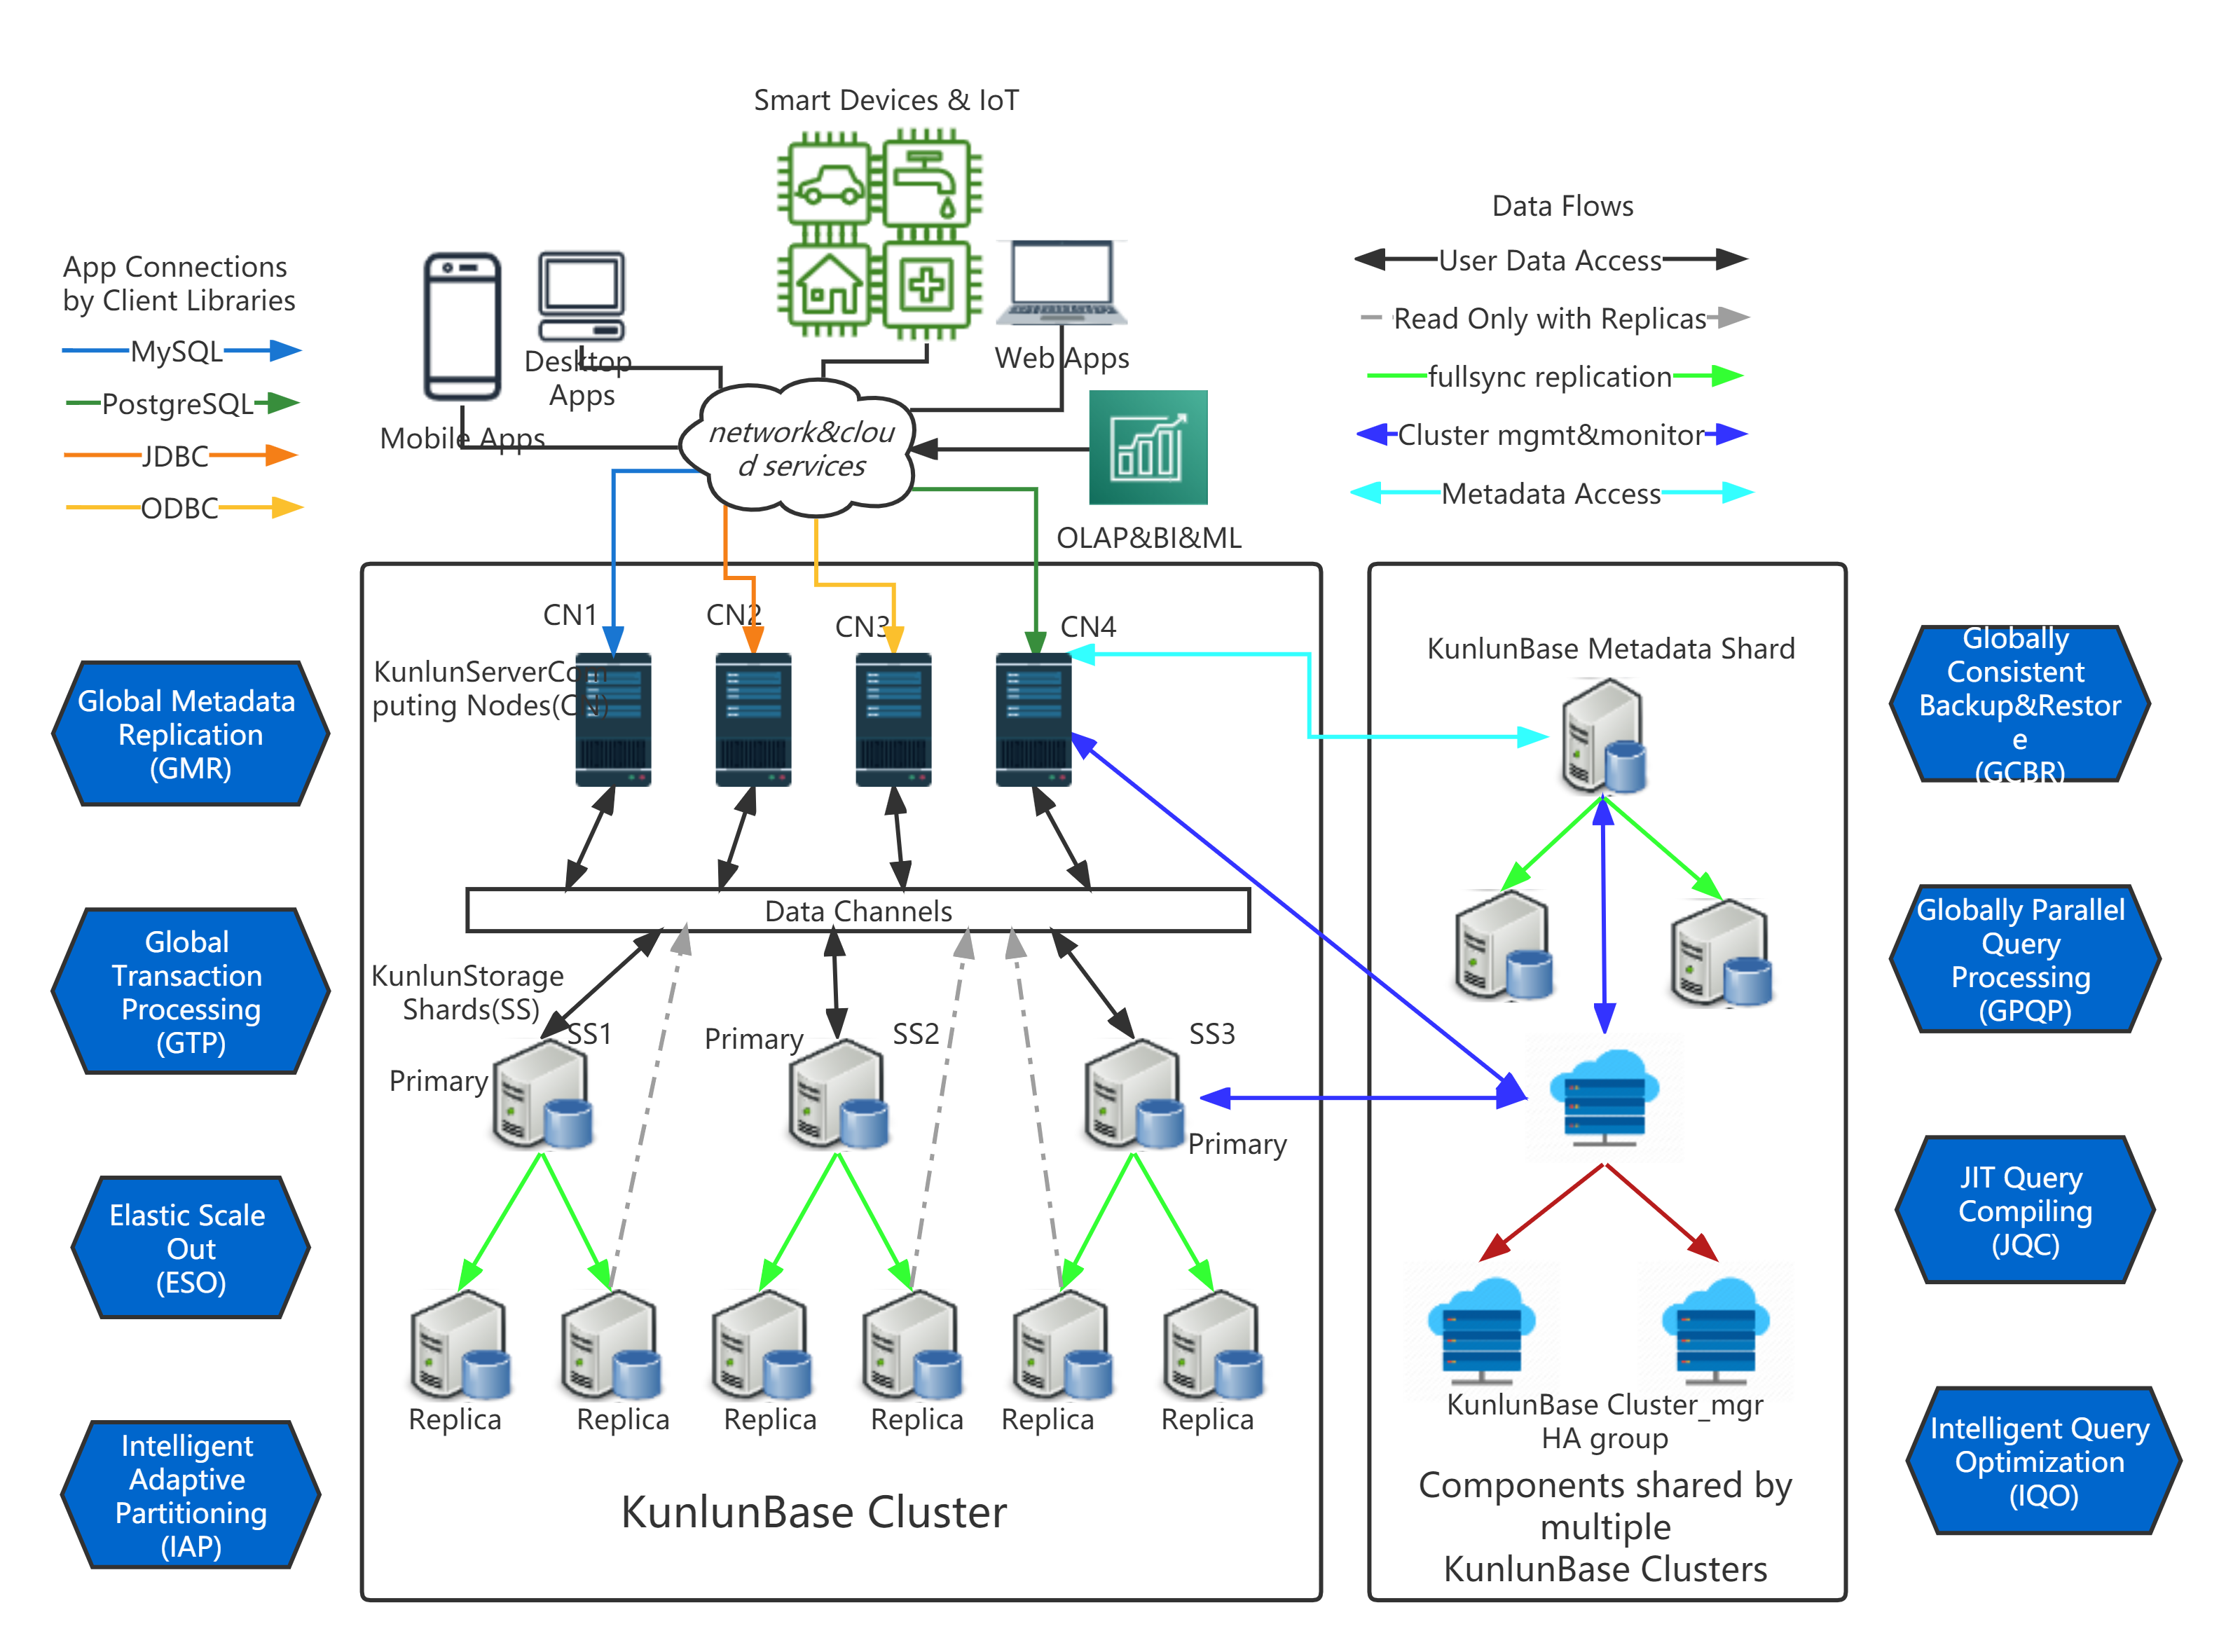
The overall architecture of KlustronDB is mainly composed of a computing layer and a storage layer. The computing layer is responsible for SQL response, interpretation, execution, etc., while the storage layer is responsible for data storage management. The data in the storage layer is stored using a multi-replica storage mechanism, and the replica (secondary copy) maintains consistency with the primary node through KlustronDB's unique full synchronization (fullsync) technology.
In general production use, the main purpose of the standby nodes of each shard in a KlustronDB cluster is to be automatically promoted to the new primary node by KlustronDB when their primary node fails. When in the standby role, they do not accept direct data processing requests from applications. Therefore, the hardware configuration of standby Klustore instances should generally be the same as that of the primary nodes so that they can be upgraded to primary nodes when needed and possess sufficient hardware resources. At the same time, this means that under normal, non-failover conditions, the resource utilization of the standby Klustore instances is relatively low.
KlustronDB has transparent and automatic read-write separation capabilities, allowing it to fully utilize the hardware resources of all standby machines and provide the highest possible performance. KlustronDB's Kluscomp instances can automatically and transparently send read-only operations to the standby node of the target shard, which can significantly reduce resource competition and consumption on the shard's primary node for read-only queries, lower the primary node's load, thereby increasing its throughput and reducing the average execution time of various statements, enhancing the overall throughput and performance of the cluster.
2. Principle of Implementation
The read-write separation of KlustronDB is controlled and executed by the distributed query processor on the Kluscomp instances. KlustronDB will automatically check whether the user's SQL statement simultaneously meets the following conditions, and if it does, it will automatically enable read-write separation for that statement.
- The current SQL type is select;
- User-defined functions (i.e., functions created with the create function statement) are not included in SQL, unless the current transaction is explicitly marked as read-only.
- If not in an explicit transaction (autocommit=on), read-write separation is allowed; if the statement is in an explicit transaction, the following must be met:
- If it is in a read-only transaction, read-write separation is allowed;
- If it is in a read-write transaction, then the transaction has not yet updated any data;
The distributed query optimizer will issue the corresponding data read commands to a certain replica node of the target shard for execution.
KlustronDB will choose which replica node in the target storage shard to send the select statement to based on the following rules:
- Select according to the weight value (ro_weight) of each Klustore instance of a shard, giving priority to higher weights;
- According to network latency (ping), that is, the delay of network packets between the primary and standby nodes of this shard, prioritize selecting the standby node with lower latency;
- According to the replication latency of each replica node of the shard, prioritize selecting the replica node with lower replication latency;
3. Configuration Implementation
Typical Scenario: A certain OLTP business system has a large number of query operations. During peak business periods, the database response speed slows down, leading to business performance issues. Upon inspection, it was found that the IO resource utilization of the primary Klustore instance had reached a bottleneck, while the IO resource utilization of the standby node was low.
The above scenarios can solve system performance issues through a read-write separation solution, without the need to modify the application or add hardware configurations. By implementing read-write separation, performance issues can be resolved.
Instructions for use:
Step 1: Set parameters and enable read-write separation
Use one of the following methods to turn on the read-write separation switch. Choose a level based on actual needs and scenarios.
- Turn on the read-write separation switch in the database session
This setting is only effective within the lifetime and scope of this session, has no effect in other sessions, and will become invalid after the session ends.
set enable_replica_read = on -- (on 开启读写分离, off 关闭)。
- User level enabled
This setting remains effective in all of the user's sessions every time the user logs in again to any Kluscomp instance of this KlustronDB cluster. It is also effective even after the Kluscomp instance restarts.
alter user abc set
enable_replica_read = true;
- Enable at the Kluscomp instance level
Make the following settings in the configuration file, then save the configuration file and restart this Kluscomp instance or reload the configuration file. After setting this method, it will be effective for all sessions of this Kluscomp instance, even after the Kluscomp instance is restarted. However, it will not be effective for other Kluscomp instances in this cluster.
enable_replica_read=on
- Enabled for all users across the entire cluster
This method applies to all existing users in this cluster as well as all users created in the future. It is effective for all sessions on any Kluscomp instance of this KlustronDB cluster.
alter system set
enable_replica_read = true;
Step 2: Log in to the database and configure the read-write separation strategy.
Set the following parameters to enable the read-write separation strategy:
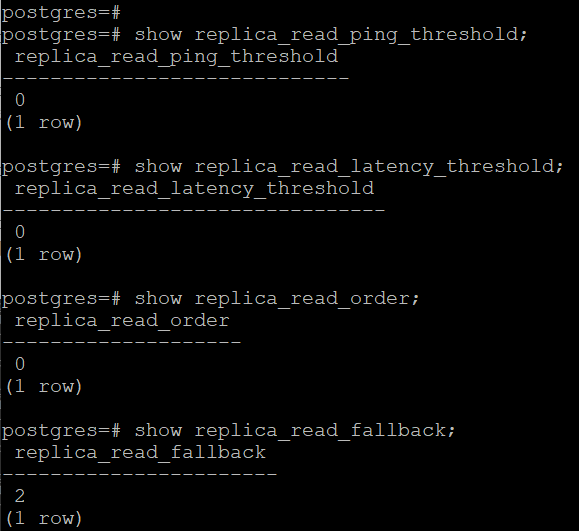
replica_read_ping_thresholdPing latency threshold from the Kluscomp instance to the backup node. If it exceeds this threshold, the backup node will not be used. 0 means this factor is not considered;
replica_read_latency_thresholdThreshold for primary-backup synchronization delay; if it exceeds this threshold, the backup node will not be used. 0 means this factor is not considered;
replica_read_order, choose backup machine priority: 0, by weight; 1, by ping latency; 2, by primary-backup synchronization delay;If the first-priority condition can already provide the most suitable standby node, use it; if multiple optimal ones are obtained, then consider the remaining selection criteria.
replica_read_fallbackThe fallback strategy for the backup machine, that is, what to do if the backup machine is not accessible. The options are as follows:
replica_read_fallback=0, directly reports an errorreplica_read_fallback=1, choose any standby machine to accessreplica_read_fallback=2, select the primary node of the target shard to read the data required for this query
Step 3: Check & set weights (optional).
In the cluster environment described in this article, the KlustronDB database cluster consists of two shards (shard1, shard2). Shard1 has a shard_id = 1 and contains 3 replicas (with IDs 1, 2, and 3, where ID 1 is the primary node, and IDs 2 and 3 are secondary nodes).
Through configuration, you can set the preferred standby server for read-only operations.
Set node3 of Shard1 as the preferred standby (because node2 is located in a different data center, the latency is too high):
update pg_shard_node set ro_weight=2 where
port=6006;
Select * from pg_shard_node ;
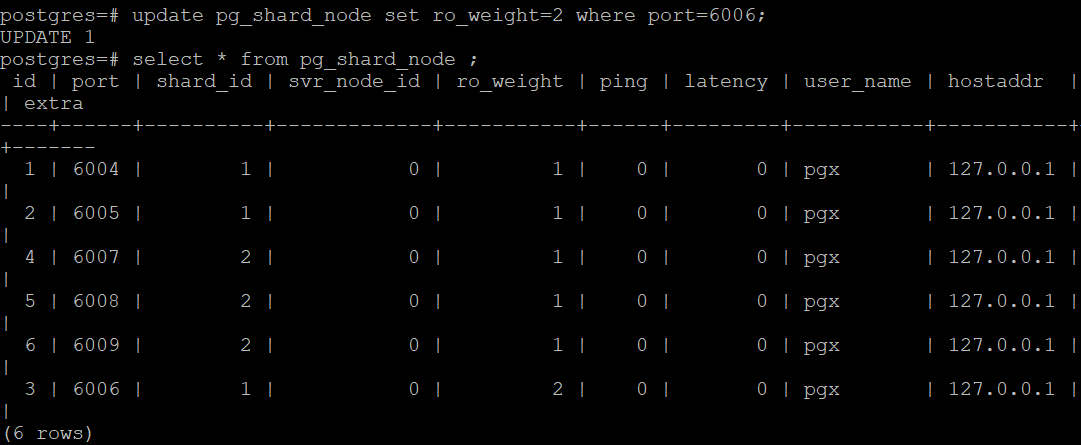
Node3 of Shard1 has the highest weight (ro_weight=2)
Step 4: Execute the query to verify read-write separation (optional).
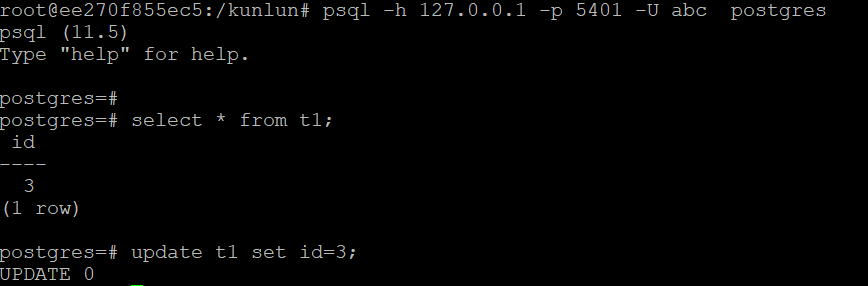
By setting log_min_messages to ‘debug1’, SQL statement execution information can be output to the log, making it easier to check the target Klustore instances where SQL is issued (do not set this in a production system, otherwise it will affect performance).
Check the logs of the Kluscomp instances to confirm read-write separation. 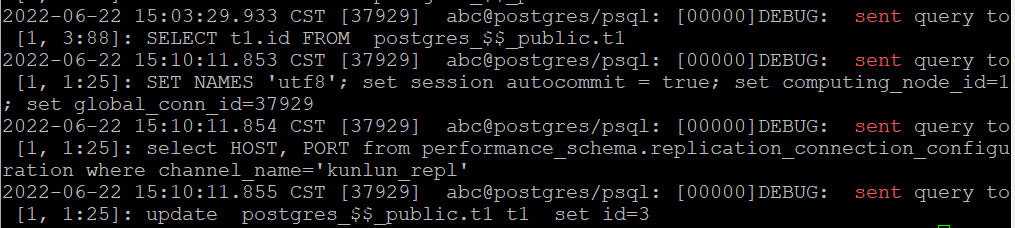
From the logs, it can be seen that the SQL read-only statement (select ti.id from t1) was issued to shard1, node 3 (the replica with the highest weight), while the update statement (update t1 set id=3) was executed on the primary node, shard1, node 1.
Conclusion
The above process verifies the implementation of read-write separation for the user. Read-only statements are routed to the replica nodes, reducing the IO resource usage of the primary node and improving the overall system performance.